A Google Ads campaign sends traffic to your landing page. Each visitor arrives with a unique gclid identifier appended to the URL, and none of them hit the cache: every request goes all the way to the origin, with the page regenerated from scratch, resulting in the worst TTFB on the site. The paradox can be summarized in one sentence: the most expensive traffic receives the worst experience.
The cause lies in a detail few teams examine: for all caches in the chain, two identical URLs differing only by a ?utm_source= are treated as two distinct resources. Each campaign thus creates new cache entries for content already stored, and this silent fragmentation divides the hit rate without triggering any alerts.
This guide picks up where SEO articles leave off: the cache key, its measurement, fixes at each level, and the new No-Vary-Search header that has moved from the Chromium lab to multi-engine support with Firefox 154. One question guides the entire discussion: how many times are you paying for the same page?
Why does the same page become multiple different resources?
A cache compares each incoming request to what it already holds using a key, and this key defaults to the entire URL, including the query string. The addresses /article and /article?utm_source=newsletter are therefore two distinct objects: identical content, doubled storage, divided hit rate.
The behavior is not an implementation flaw, but a precaution: a parameter can change the response, so the cache treats each variant as a separate page. At Cloudflare, the default cache key is composed of the host, path, and the full query string, meaning that /promo.jpg?utm_campaign=spring and /promo.jpg?utm_campaign=fall occupy two distinct locations at the edge for the same binary file.
The effect is combinatorial, not additive. A site with 100,000 URLs, where each address circulates with four parameter variants, manages 400,000 keys for the same content, and each variant starts from scratch: its first visitor pays for a full regeneration, the very thing that the cache at all levels was supposed to prevent. Shared memory among visitors dilutes as campaigns multiply.
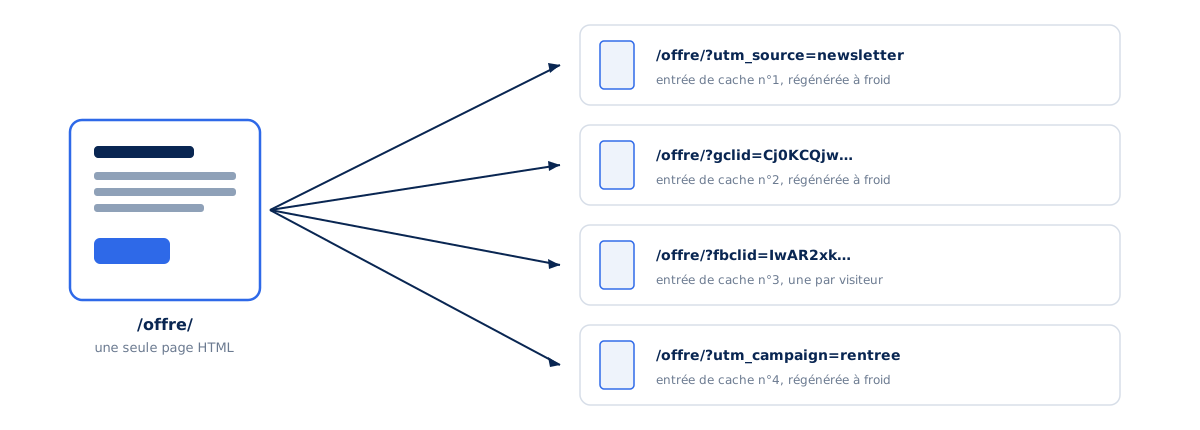
The worst offender deserves to be named: fbclid. Facebook adds it to every outbound click, including organic shares and comment links, with a unique value per click. A viral page on Facebook means as many cache entries as visitors, without any advertising budget at play: fbclid does more damage than all UTMs combined, and it heralds the next question, that of inventory.
Which parameters fragment the cache?
All tracking parameters, meaning several dozen names listed in the default exclusion list of WP Rocket alone: the complete utm_ family, gclid and its successors gbraid and wbraid, fbclid, msclkid, ttclid. The following table groups the families to know by ad network.
| Family | Parameters |
|---|---|
| Google Analytics and Ads | utm_source, utm_medium, utm_campaign, utm_term, utm_content, utm_id, _ga, _gl, gclid, gbraid, wbraid, gad_source |
| fbclid, fbadid, fb_action_ids, fb_source | |
| Other Ad Networks | msclkid (Microsoft Ads), ttclid (TikTok), yclid (Yandex), li_fat_id (LinkedIn) |
| Adobe | ef_id (Advertising Cloud), s_kwcid (Analytics) |
| Advertising in AI Assistants | oppref (ChatGPT Ads, OpenAI) |
| Emailing and Affiliate Marketing | mc_cid and mc_eid (Mailchimp), dm_i (Dotdigital), vgo_ee (ActiveCampaign), sscid (ShareASale) |
The best-maintained reference remains the list that WP Rocket ignores by default, regularly enriched, as evidenced by the recent additions gbraid, wbraid, and gad_source. Added depending on the site are call tracking parameters, those from WordPress extensions like cn-reloaded or age-verified, and identifiers specific to each emailing tool: the ecosystem produces them faster than they can be inventoried.
A real-life case during the writing of this article illustrates this. During an ongoing optimization, a client was advertising on OpenAI's new platform, with ads displayed in ChatGPT, and their landing pages were receiving a parameter no one had yet inventoried: oppref. The OpenAI documentation presents it as the OpenAI click reference, added at the end of the URL as ?oppref=gAAAAAb123, which the measurement pixel copies into a first-party cookie __oppref: it's ChatGPT's gclid, nothing more, nothing less.
Large language models are starting to offer this type of promotion, and each platform comes with its own click identifier. This is handled like all others: it never changes the server's response, it's read client-side, so it's excluded from the cache key at every level while remaining intact in the displayed URL, where the pixel retrieves it.
OpenAI also asks to preserve this parameter across redirects, which once again condemns the cleanup 301. The lesson goes beyond the specific case: an inventory of parameters has an expiration date, and it is re-read with each new campaign launched by marketing.
The methodological point matters more than the list itself: it is not copied, it is established site by site. The inventory distinguishes parameters that change the response, such as page, s, id, lang, variant, or orderby, from those that never change it, and applies a single rule to edge cases: any ambiguous parameter remains in the key. It remains to be seen where, physically, this key is calculated.
At what levels of the chain does the problem arise?
At least four levels: the browser's disk cache, the Speculation Rules preloading cache, the CDN edge, and the server's application cache. Each calculates its own key, each corrects itself separately, and the least well-configured link dictates the final experience.
| Level | Default key | Where to act |
|---|---|---|
| Browser disk cache | Full URL | No-Vary-Search (Chrome 141+, Firefox 154+) |
Prefetch and prerender (Speculation Rules) | Full URL | No-Vary-Search (Chrome 121+) and expects_no_vary_search |
| CDN / edge | Host + path + query string | Cache Rules, Transform Rules, custom key |
| Application cache (WP Rocket, LiteSpeed, FastCGI, Varnish) | Variable depending on the tool | Plugin or server configuration |
| bfcache | Out of scope | No-Vary-Search with no effect |
Reading the table vertically is the correct approach: correcting one level does not correct the others. A CDN with a perfectly configured key does not prevent the browser from re-downloading a page it already has under a different query string, and vice versa. Each level is handled with its own tools, in the order traffic traverses them, and the variants stored at the network edge weigh all the more because the hit rate directly conditions the TTFB of the first visit.
A prerequisite nullifies the entire reasoning if it is missing: the HTML must be cacheable. A page served with Cache-Control no-store benefits from none of the fixes in this article, as no cache is allowed to store it: checking cacheability comes before any key configuration, and this check begins with measurement.
How to measure fragmentation on your own site?
Three instruments are sufficient: server logs to inventory the received parameters, the CDN hit rate segmented with and without query strings, and DevTools to check on a case-by-case basis. One point is counter-intuitive: CrUX will never show the problem, by design.
The inventory starts on the server side. A command line extracts parameter names from the access log and sorts them by frequency, yielding in seconds the actual list, not the supposed list:
# Top 40 des parametres recus, tries par frequence
awk '{print $7}' access.log | grep '?' | cut -d'?' -f2 \
  | tr '&' '\n' | cut -d'=' -f1 | sort | uniq -c | sort -rn | head -40
On the CDN side, the segmented hit rate tells the full story: 90% hit rate for URLs without parameters and near-zero for parameterized URLs signal fragmentation. In DevTools, the Size column of the network panel confirms on a case-by-case basis, comparing a visit with and without parameters. Debugging No-Vary-Search is still done the old-fashioned way: no DevTools integration exists to date, a limitation that Harry Roberts publicly regrets in his reference article.
Don't look for the problem in PageSpeed Insights or the Search Console's Core Web Vitals report. The CrUX methodology removes query parameters and fragments from URLs, precisely to aggregate all experiences of the same page: the degraded TTFB from paid traffic is indeed in the data, but drowned in the average, as explained in our comparison between field data and lab data. Only RUM that does not normalize URLs, or the hit rate itself, makes the phenomenon visible: invisibility in standard tools explains its longevity.
What is the No-Vary-Search header and how do you write it?
No-Vary-Search is an HTTP response header that declares which parts of the query string can be ignored when matching the cache. Documented on MDN and standardized at the IETF in the httpbis no-vary-search draft, it allows the cache to reuse an already stored resource despite different parameters.
Confusion with Vary is frequent and deserves to be cleared up right away. Vary declares that the response depends on request headers like Accept-Encoding, and therefore adds variants; No-Vary-Search declares that the response does not depend on certain URL parameters, and removes them. Both headers act on the same key, in two opposite directions. Its five forms are written in structured fields, the syntax of RFC 8941, with lists in parentheses and values in quotes:
# L'ordre des parametres n'est plus discriminant
No-Vary-Search: key-order

# Tous les parametres sont ignores
No-Vary-Search: params

# Seuls ces parametres sont ignores (liste noire)
No-Vary-Search: params=("utm_source" "utm_medium" "gclid" "fbclid")

# Tout est ignore sauf ces parametres (liste blanche)
No-Vary-Search: params, except=("q" "page")

# Combinaison
No-Vary-Search: key-order, params, except=("id")
The choice between the two main forms is a choice of posture. The except=() form ignores everything except declared functional parameters: it is suitable for a site whose consumed server parameters are exhaustively known. The explicit params=() form only removes named parameters from the key: this is the cautious posture everywhere else, because the whitelist protects against forgotten parameters, while the blacklist lets them fragment. Sending the header itself takes one line on the server side:
# Apache (.htaccess ou vhost)
Header set No-Vary-Search "params=(\"utm_source\" \"utm_medium\" \"utm_campaign\" \"gclid\" \"fbclid\")"

# Nginx
add_header No-Vary-Search 'params=("utm_source" "utm_medium" "utm_campaign" "gclid" "fbclid")' always;
On Apache, the directive joins the headers already set in your root configuration file, with the scope precautions that apply there. We still need to know which browsers actually honor this declaration today.
What is its level of support today?
Better than a year ago, and now multi-engine: Chrome applies it to the preloading cache since version 121 and to the HTTP disk cache since version 141, Firefox enables it by default since version 154 of August 2026, and WebKit has no official position. The structuring limit is elsewhere: no CDN interprets it yet in its cache key.
On the Chromium side, deployment occurred in three stages: the Speculation Rules prefetch cache in January 2024 with Chrome 121, then prerender, and finally the general disk cache with Chrome 141 in September 2025 on desktop, with Android availability following around version 144. Mozilla confirmed the trajectory with a positive intent to ship and then default activation in Firefox 154, released on August 18, 2026: the header has gone from a Chromium curiosity to a true multi-engine feature in less than a year.
The nuance that prevents us from claiming victory concerns the edge. The authors of the specification represent Fastly, Akamai, and Cloudflare, but none of these CDNs currently integrate No-Vary-Search into their cache key calculation: the header acts on the browser, not on the edge, and normalization on the CDN side remains entirely manual.
Deployment, on the other hand, carries no risk of regression: a cache that does not understand the header ignores it and falls back to exact URL comparison, the historical behavior. Setting the header today improves recent browsers without degrading anything else, making it a progressive enhancement in the strict sense, while waiting for the edge to catch up.
Is your site as fast as your visitors expect?
What to do in the meantime on the CDN side?
Three approaches exist across all major CDNs, from the cleanest to the most radical. At Cloudflare, they are implemented through Cache Rules and Transform Rules, with the latter available even on the free plan:
- customize the cache key by excluding tracking parameters, with the URL remaining intact from end to end ;
- remove parameters before caching via a Transform Rule, with the URL seen by the visitor remaining unchanged, only the one sent to the origin being cleaned ;
- ignore the entire query string, to be reserved for static resource paths, as on HTML it breaks internal search, pagination, and filters.
The second approach is written in one expression, in a dynamic URL Rewrite rule, thanks to the remove_query_args() function of the rules language :
# Transform Rule > URL Rewrite > Query > Rewrite to... > Dynamic
remove_query_args(http.request.uri.query,
  "utm_source", "utm_medium", "utm_campaign", "utm_term",
  "utm_content", "utm_id", "gclid", "gbraid", "wbraid",
  "gad_source", "fbclid", "msclkid", "ttclid", "oppref", "_ga", "_gl")
A warning from the Cloudflare documentation deserves to be quoted verbatim : when customizing the cache key by enabling URL normalization, you must also normalize the URLs sent to the origin, otherwise the key and the actually served request will diverge, opening the door to cache poisoning through misalignment. With the edge configured, the application layer remains, with WordPress at the forefront.
And on the WordPress side, how to regain control ?
The two dominant caching plugins have opposite flaws : WP Rocket ignores tracking parameters by default and serves the cache file from the clean URL, so that /about-us/?gclid=abc and /about-us/?gclid=def receive the same page, while LiteSpeed Cache caches each query string individually by default.
On LiteSpeed, the fix is in the Drop Query String setting, by pasting the list of parameters to discard, one name per line :
# LiteSpeed Cache > Cache > Drop Query String
utm_source
utm_medium
utm_campaign
utm_term
utm_content
gclid
gbraid
wbraid
fbclid
msclkid
oppref
Sending No-Vary-Search from WordPress itself goes through the send_headers hook, excluding pages whose response depends on context, such as the cart, account, or search :
// functions.php : envoyer No-Vary-Search sur les pages cachables
add_action('send_headers', function () {
    if (is_search() || is_cart() || is_checkout() || is_user_logged_in()) {
        return; // reponse dependante du contexte : ne rien declarer
    }
    header('No-Vary-Search: params=("utm_source" "utm_medium" "utm_campaign" "gclid" "fbclid")');
});
On an Nginx FastCGI cache or Varnish, the key is defined directly in the configuration, with a publicly documented pitfall : the combination of parameters. A URL that carries both a fbclid and a functional parameter must be removed from the cache or retain the functional parameter in its key, and a rule that is too simple, written for an isolated parameter, lets it pass : rules must be tested on combined URLs, never on textbook cases. Moreover, the declared list must be correct.
What happens if we choose the wrong parameter ?
Declaring a parameter that the server reads as ignorable results in serving erroneous content from the cache. On an account page, a cart, or an internal search, this is a data leak between visitors : a declaration error is a security incident, not a simple display bug.
The security review conducted during Chrome-side development stated it plainly: an overly broad setting for No-Vary-Search, combined with server-side bugs, can allow an attacker to control the content displayed to the user. The risk is comparable to that of other mechanisms that personalize the response, but it exists, and it justifies the caution that Harry Roberts summarizes in his header guide published in May 2026, where he only recommends the header for parameters that are purely for analytics or purely decorative:
I prefer to be served the correct page a little more slowly than the wrong page quickly.
Harry Roberts, in his article Better Browser Caching with No-Vary-Search, CSS Wizardry, May 2026
The operational rule can be stated in one sentence: a parameter should only be declared ignorable if it has been verified that the server never reads it, neither in PHP, nor in a plugin, nor in a rewrite rule. When in doubt, it remains in the key, and this same discipline applies to the marketing objection that inevitably arises as soon as we talk about cleaning up parameters.
Does cleaning up parameters break marketing attribution?
No, provided the correct treatment is chosen. Analytics tools read parameters in the URL displayed by the browser, on the client-side: as long as this URL remains intact, attribution sees nothing. The following table distinguishes the three treatments and their respective consequences.
| Treatment | URL seen by the visitor | Client-side attribution |
|---|---|---|
| Excluding the parameter from the cache key | Unchanged | Intact |
| Rewriting the URL sent to the origin | Unchanged | Intact on the browser side, lost in server logs |
301 Redirect to the cleaned URL | Modified | Broken, with the latency of the redirect thrown in |
The first two approaches are invisible to Google Analytics, which reads document.location in the browser, before any cache considerations. Only the redirect breaks attribution, and it adds a full network round trip whose cost is detailed in our guide to HTTP status codes: the 301 is the only treatment to avoid, and it is precisely the first one found in tutorials.
One recommendation gets everyone to agree, marketing included: never place UTM parameters on internal links. The practice pollutes the crawl, creates cache variants, and above all rewrites the campaign of an already ongoing session, which distorts attribution instead of enriching it: internal navigation tracking is done via events, never via parameters. The SEO aspect of the subject deserves the same reframing.
What is the real SEO impact of URL parameters?
There are no penalties: ordinary parameter-based duplications trigger consolidation, not sanctions. The real costs are the dilution of the link signal between variants, wasted crawl budget, and the risk of displaying the parameterized version in the results.
The standard answer is a single tag: the self-referencing canonical to the clean URL, present on each page, which tells search engines which variant to consolidate. Bad ideas do more damage than the problem itself: returning a 404 for parameterized URLs or blocking them in robots.txt causes the loss of incoming links pointing to these variants, a mechanism detailed in our analysis of the SEO impact of web performance.
A reflex inherited is also to be corrected: the URL Parameters tool in Search Console, still cited by many guides, was removed by Google in April 2022, deemed useful for only about 1% of configurations: guides that still mention it are outdated.
The SEO issue is therefore real but secondary: it is resolved with a well-placed canonical, while the caching issue is resolved at four levels. It remains an area where the two meet, that of preloading, where parameters ruin an entire mechanism if they are not declared.
What does this have to do with Speculation Rules?
A prefetch or a prerender is only useful if the clicked URL exactly matches the prefetched URL, and a simple gclid is enough to cause failure: the page is ready, the browser discards it. No-Vary-Search was born in this context, with Chrome 121, to reuse a prefetched page despite different parameters.
The mechanism is completed on the rules side with the expects_no_vary_search field, which announces the expected header value to the browser even before the response arrives: it can thus decide to wait for an ongoing prefetch rather than launching a concurrent request. Google Search uses it for its own results pages, with a significant latency gain measured during its experiments, documented by Chrome for Developers. The rule is written as follows:
<script type="speculationrules">
{
  "prefetch": [{
    "urls": ["/offre/"],
    "expects_no_vary_search": "params=(\"utm_source\" \"gclid\" \"fbclid\")"
  }]
}
</script>
A final precaution closes the chapter, specific to prerender: the page may have been prerendered with different parameters, or even none. Initially, location.href holds the prerendered URL, and the browser replaces it with the final URL at the time of activation: any JavaScript that depends on query parameters, especially attribution scripts, should only execute after the prerendered page is activated, a mechanism detailed in our guide to instant navigation via prerendering.
Cleaning up parameters: trade-off or obvious?
Cleaning up parameters does not pit marketing against technical: when done well, it costs nothing for attribution, and it gives paid traffic the experience its acquisition cost justifies. It requires an inventory, staged adjustments, and the discipline to leave in the cache everything you are not sure about.
The economic equation is simple: each useless cache variant makes you pay twice for the same content, once for click acquisition, and once for regenerating a page that already existed in the cache, resulting in a server response time degraded precisely for the most expensive visitors. The technical terms crossed here are taken up in the language of web performance for teams new to the subject: the bill is double and perfectly avoidable.
Measuring your own fragmentation, arbitrating ambiguous parameters, and deploying fixes without breaking attribution falls under instrumented diagnostics, from server logs to RUM. This is the exact scope of a web performance audit, and its implementation is that of a performance optimization carried out stage by stage: the cache key is now a chapter just like images or fonts.